data · · 9 Min Read
Metric Definitions: Examples and a Practical Template
Two dashboards, two numbers for one KPI? Use this metric definition template and churn example to align calculations and check AI-generated reports.

Metric definitions: why dashboards disagree and how to fix them
A metric definition is the agreed specification for a business measure: what it counts, how it is calculated, which records qualify, and which reporting period it covers. It should let another person reproduce the number without guessing what you meant.
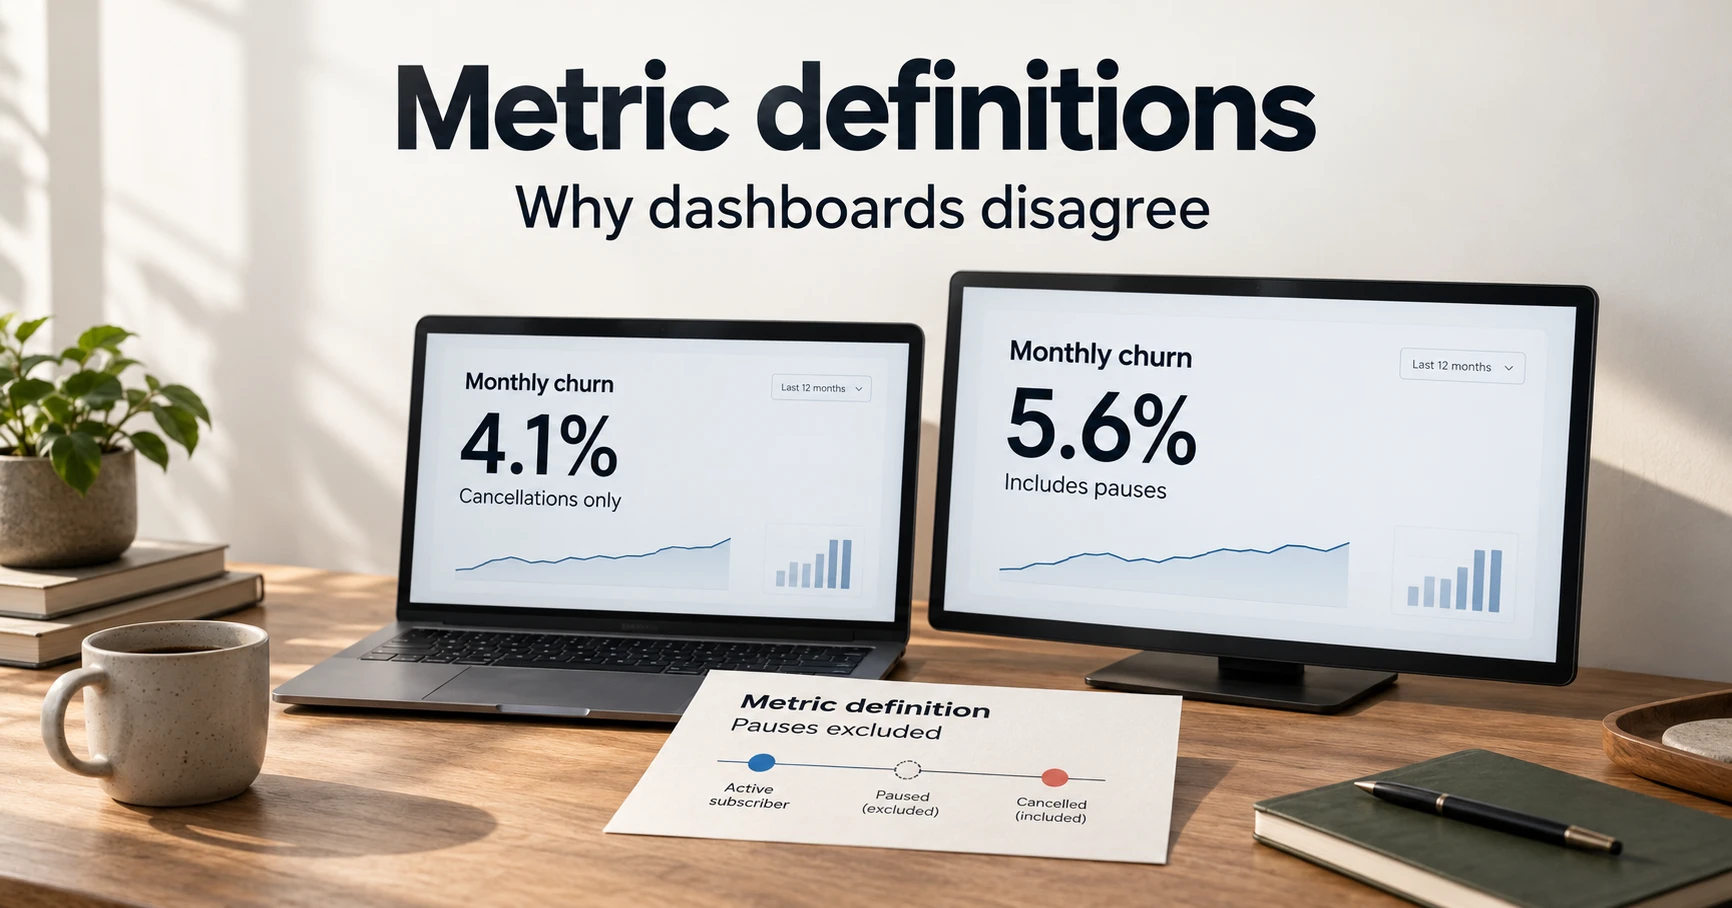
When two dashboards show different numbers for the same KPI, compare those definitions before choosing which report to trust. One may include paused subscriptions in churn. Another may count only cancellations. Both can run without an error and still answer different questions.
This guide gives you a metric definition template, a worked churn example, and a way to check that future reports use the rule your team agreed on.
Why dashboards show different numbers for the same KPI
Start by checking whether the reports use the same calculation, records, and time window.
| What differs | What to check | Example |
|---|---|---|
| Formula | Numerator, denominator, aggregation | Average order value before or after refunds |
| Population | Which people, accounts, or events qualify | Paid customers only, or free trials too |
| Exclusions | Filters that remove records | Paused subscriptions counted as churned |
| Event boundaries | Where a duration starts and ends | Support response time from ticket creation, or from agent assignment |
| Time rules | Date field, timezone, reporting window | Invoices issued this month, or payments received this month |
| Data state and access | Refresh time, source version, permissions | Yesterday's full extract versus today's region-filtered view |
Definitions explain some mismatches. Others come from duplicate joins, missing records, stale extracts, or query errors. If the definitions match, inspect the underlying rows and refresh times next.
Two legitimate definitions can also coexist. “Gross sales” and “sales after refunds” answer different questions. Give each a clear name so nobody compares them as if they were interchangeable.
Metric definition example: 4.1% churn or 5.6% churn?
Consider this illustrative monthly subscription report:
- 1,000 eligible paid subscriptions were active at the start of September.
- Of those, 41 cancelled during September and remained cancelled at month-end.
- A separate 15 paused during September without cancelling.
A cancellation-only calculation gives 41 ÷ 1,000 × 100 = 4.1%. A report that treats those pauses as churn gives 56 ÷ 1,000 × 100 = 5.6%.
The arithmetic is correct in both. The disagreement is whether a pause counts as churn. The numbers here are invented to demonstrate the calculation; they are not customer results or an industry benchmark.
For this example, agree on the following definition:
Monthly paid subscription churn rate is the percentage of eligible subscriptions active at the start of the month that cancel during the month and remain cancelled at month-end. Pauses do not count as cancellations.
Both the numerator and denominator refer to the same starting group. A subscription that starts and cancels during September belongs in a separate measure; adding it only to this numerator would mix populations.
This is one possible business rule. Your company may need a different treatment of pauses or reactivations. Document that choice before anyone calculates the KPI.
A metric definition template your team can use
A one-sentence explanation is useful, but it rarely captures every decision needed to reproduce a number. Record the formula, time rules, source, and exceptions alongside it.
Copy this template for the metric your team disputes most:
Metric name:
Business question it answers:
Plain-language definition:
Formula and unit:
Counting unit (account, subscription, user, order, event):
Included population:
Exclusions and edge cases:
Date field, timezone and reporting window:
Source tables or approved model:
Refresh time and data snapshot:
Business owner:
Technical maintainer:
Approved test case and expected result:
Definition version and effective date:
Policy for recalculating historical reports:
For the churn example, a completed definition could look like this:
| Field | Illustrative definition |
|---|---|
| Name | Monthly paid subscription churn rate |
| Purpose | Track cancellations from the subscriptions active at the month's start |
| Formula | Eligible starting subscriptions that cancel and remain cancelled at month-end ÷ all eligible starting subscriptions × 100 |
| Counting unit | Unique subscription ID; count each subscription once |
| Included population | Paid subscriptions active at 00:00 UTC on September 1, 2026 |
| Exclusions | Trials, internal and test subscriptions, and subscriptions already paused at the start |
| Edge cases | A pause alone is not churn. Count a starting subscription once if cancellation takes effect during the month and it is cancelled at month-end, including after an intervening reactivation. Exclude subscriptions active or paused at month-end. |
| Time window | Cancellation effective time from September 1 at 00:00 UTC up to, but excluding, October 1 at 00:00 UTC |
| Source | Approved billing model with subscription history; today's status alone cannot reconstruct the starting population |
| Data snapshot | Fixed September test snapshot; production reports display their refresh time |
| Ownership | Finance approves meaning; the analytics maintainer implements and tests it |
| Expected result | 41 cancellations from 1,000 eligible subscriptions = 4.1% |
| Change policy | Record the version, effective date, and whether earlier reports must be recalculated |
The expected result needs a fixed dataset or a recorded snapshot. Otherwise, a backfilled cancellation can change September's answer even when the calculation has not changed.
Start with the numbers leadership actually uses
Begin with five to eight recurring metrics as a practical starting point, not a requirement. Choose the ones people use to make decisions, especially those someone rechecks every week.
Assign a business owner who can settle what each metric means. Give the data team responsibility for implementing and testing that decision. One person may hold both roles in a small team; the responsibilities should still be clear.
When someone proposes a change, record why it is needed and when it takes effect. Decide whether to recalculate history or mark a break in the series. A chart that silently changes definitions can make a policy change look like a change in business performance.
For help choosing which measures deserve this attention, see what makes a metric a KPI.
Put metric definitions where reports use them
Keep a readable reference for people, and connect it to the calculation used by dashboards and AI tools. A document becomes stale if the live query changes without it.
If your team maintains a semantic layer, define the approved metrics there and route supported reports through it. For example, the dbt Semantic Layer centralizes metric definitions for use through its integrations. Our semantic layer guide explains how that approach fits into a BI setup.
If an AI tool reads business rules and examples, add the approved definition and a checked query to its context. Then test whether it follows them. A saved rule is useful evidence of intent; the resulting calculation shows whether it was applied.
A shared database alone is not a single source of truth for metrics. People can query the same rows with different filters. Consistency depends on using the same approved logic, population, and data snapshot.
How to check AI-generated reports without repeating every correction
Build a small set of checks around the decisions that can change an answer. Five to twenty questions is a manageable starting set; expand it as new failures appear.
- Test the ordinary case and the exceptions. For churn, include a cancellation, a pause, a reactivation, a trial, and an event on the month boundary. Keep expected results beside the test data.
- Make each number traceable. Keep the query, date range, filters, and data refresh time available. Review the included records when a total looks wrong.
- Save the correction in the maintained rule. Update the definition or approved example, then add a test that would have caught the mistake. A correction made only in the current chat may not govern another report.
- Rerun the checks after changes. Recheck when a definition, source model, or agent configuration changes. Hold a report for review when a critical metric fails.
- Use one recurring report as the reference. Link back to it when discussing results, with its period and refresh time visible. That gives everyone a specific version to reconcile against.
Passing a test set tells you how the tool handled those cases. It does not establish that every future question will be answered correctly. Supaboard's AI data analytics benchmark offers another example of evaluating answers on a defined dataset, with the limits of its vendor-reported results stated alongside them.
Applying the definition in Supaboard
In Supaboard, you can save business context through knowledge and rules, use approved SQL as a verified example, and inspect the SQL behind an answer.
Evals let you pair questions with expected SQL, run the agent against them, and inspect failures before updating a rule or example. Each answer in an eval run receives a score from 0 to 100. Use those results to check the questions you have tested, including the exceptions that matter to your team.
The business owner still decides what churn means. The workflow is to record that decision, test the implementation, and check it again after a change.
Frequently asked questions
What is the difference between a metric and a KPI?
A metric is a measure. A KPI is a metric selected to track progress toward an important business objective. Both need clear definitions, whether or not leadership reviews them every week.
What should a metric definition include?
Include its business meaning, formula, counting unit, eligible population, exclusions, time rules, source, owner, and a test with an agreed result. Record a version and effective date so readers can tell when the definition changed.
Where should metric definitions live?
Keep a readable reference linked to the maintained calculation. That might be a semantic layer, an approved BI model, or the rules and verified examples used by an AI agent. Test that reports use the definition.
Who should own a metric definition?
The person accountable for the business decision should approve its meaning. An analyst or analytics engineer can maintain the calculation and tests. Make both responsibilities explicit.
Can AI write metric definitions?
AI can help draft a definition and suggest edge cases. A person with business context should approve the meaning, and someone should verify the calculation against known records before the result is used.
Why do two dashboards show different numbers for the same KPI?
Compare the formula, included records, filters, event boundaries, reporting period, and refresh time. If those match, inspect the underlying rows for missing records or duplicate joins. Two reports may be measuring different things under the same label.
Related discussion: Two dashboards show different wait times. Which number would you trust?
How should a data team review dashboards built with Claude or Cursor?
Ask for the query, source, filters, reporting period, and refresh time. Check the calculation against the approved metric definition and a known test case. Assign an owner to resolve differences before the report is used for a business decision.
Related discussion: How are analytics teams handling dashboards built with Claude or Cursor?
What would make an AI-generated report reliable enough to use every week?
Each important number should be traceable to its source and reporting period. Test the report against agreed answers, flag missing or conflicting data, and save corrections in the maintained rules or approved examples. Add a regression test for each correction so the next run checks for the same mistake.
Related discussion: What would make AI financial analysis trustworthy enough to use every week?
Fix the number your team rechecks every week
Choose one disputed metric. Fill in the template, agree on its owner, and calculate it against a small, checked dataset. Use that definition in the next recurring report and keep the test for future changes.
To try this in Supaboard, connect your database, add the definition, and test the agent on questions your team can verify. Start Free.
 7 Min Read